Guardrails Before the Work, Acceptance After It
Handing real work to agents takes two records: what an agent may do before it acts, and who accepted what it produced afterward. OrgX keeps both on the same initiative.
OrgX / Journal
What we learn building AI work that carries its context forward. Experiments, engineering decisions, and the evidence behind them.
Featured field note
Open standard · Jul 22, 2026
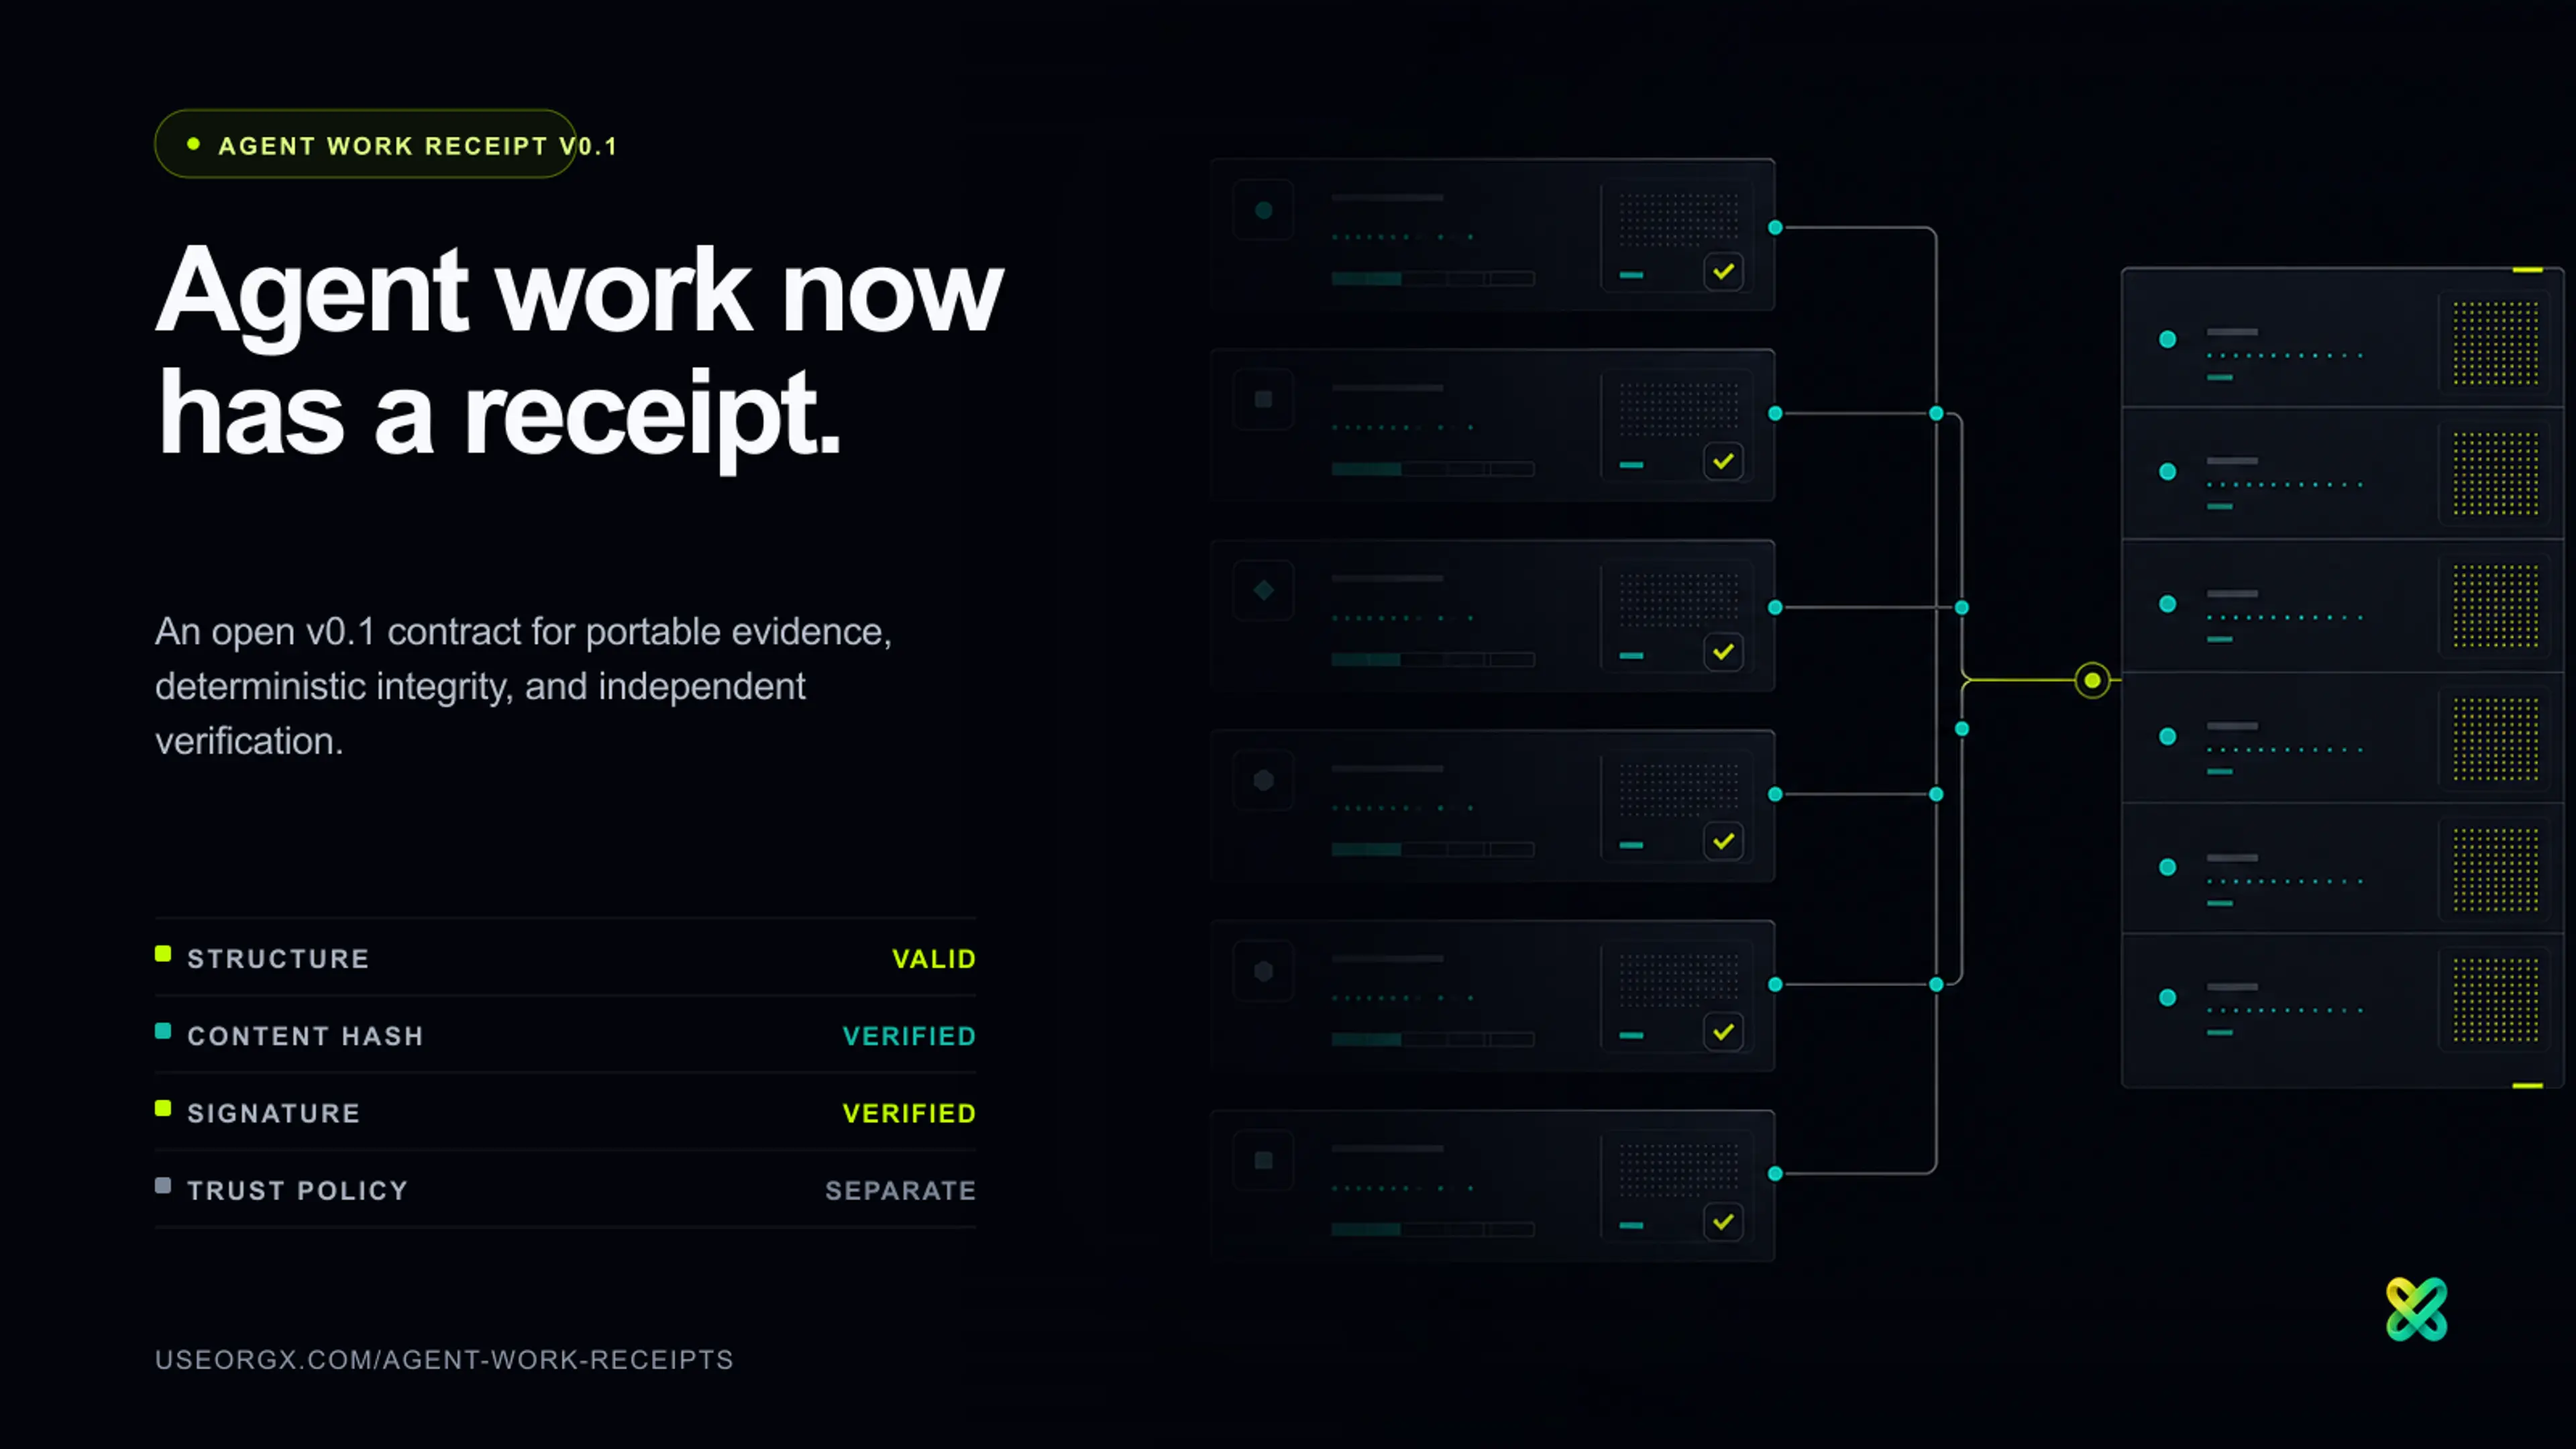
Agent Work Receipt v0.1 is an open, account-free contract for portable evidence, deterministic integrity, and independent verification across agent runtimes.
16 articles
Handing real work to agents takes two records: what an agent may do before it acts, and who accepted what it produced afterward. OrgX keeps both on the same initiative.
Braintrust and Basis made agent behavior testable. The next primitive makes the judgment cumulative: an open work receipt that binds a behavior verdict to authority, artifacts, cost, and human acceptance.
Agent Work Receipt v0.1 is an open, account-free contract for portable evidence, deterministic integrity, and independent verification across agent runtimes.
Recall infrastructure tops out at $249/month. Proof gets compared against the dispute, the audit, and the cancelled project. OrgX prices like the second list.
OrgX-Bench V1.2 adds solution-equivalence audits, counterfactual twins, contamination burn rules, statistical precision, and public corrections before any frontier headline can ship.
The OrgX autonomous initiative benchmark had a quiet rot problem: its judge panel pointed at models that no longer exist. We fixed it, re-ran the full catalog on current GA models, fixed a cost bug along the way, and tied the autonomy score to the gated-autonomy controls that now ship in OrgX.
Linear, Jira, and Notion all expose useful MCP surfaces. OrgX is taking a different bet: the fastest agent workflow is the one where one tool call becomes durable company memory, execution state, and proof.
Continuity is the missing infrastructure for AI-native companies. OrgX is the operating system that holds the thread between people, agents, decisions, and time.
We ran 136 tasks across 4 models × 4 orchestration cells × 3 dependent task sequences. Single-shot benchmarks structurally hide what agents cannot fake: cascading context. Here is the data, the surprises, and what we changed.
The first five minutes decide whether your AI tools share company memory or become six separate rooms with six separate amnesia. That is why we built OrgX Wizard.
The point was not volume. It was forcing the system to find the few ideas with enough pain, specificity, and visual tension to deserve production.
The OrgX autonomous initiative benchmark now publishes generated artifacts, independent judgments, token-level costs, and the failures that still need human review.
AI content looks like slop when a model is asked to carry taste, memory, and QA by itself. The fix is not a better prompt. It is a content system.
Wearing many hats is not a founder superpower. It is a coordination failure wearing a flattering name. The founder should not have to be the operating system.
I kept opening new Claude sessions and typing 'let me catch you up.' OrgX MCP is the continuity layer that stops founders from manually carrying context between ChatGPT, Claude, Cursor, and the rest of the stack.
How OrgX-Bench separates public mechanism runs from private headline evidence, measures benchmark error, and evaluates trustworthy initiative completion.